A simple question with a complicated answer
Imagine a supplier tells you that a shipment will be delayed by three weeks. Your first question is straightforward:
Which customer commitments could this affect?
Answering it may take more work than expected. The purchasing system tells you which components come from that supplier. Product records show where those components are used. Customer contracts contain delivery obligations. An email thread may contain a revised date, while a project update explains which orders have room in their schedules.
The information exists, but someone still has to find it, connect it and decide which details to rely on.
This is the challenge we explore in this series: how to make information spread across an organisation easier to use when a business decision depends on it.
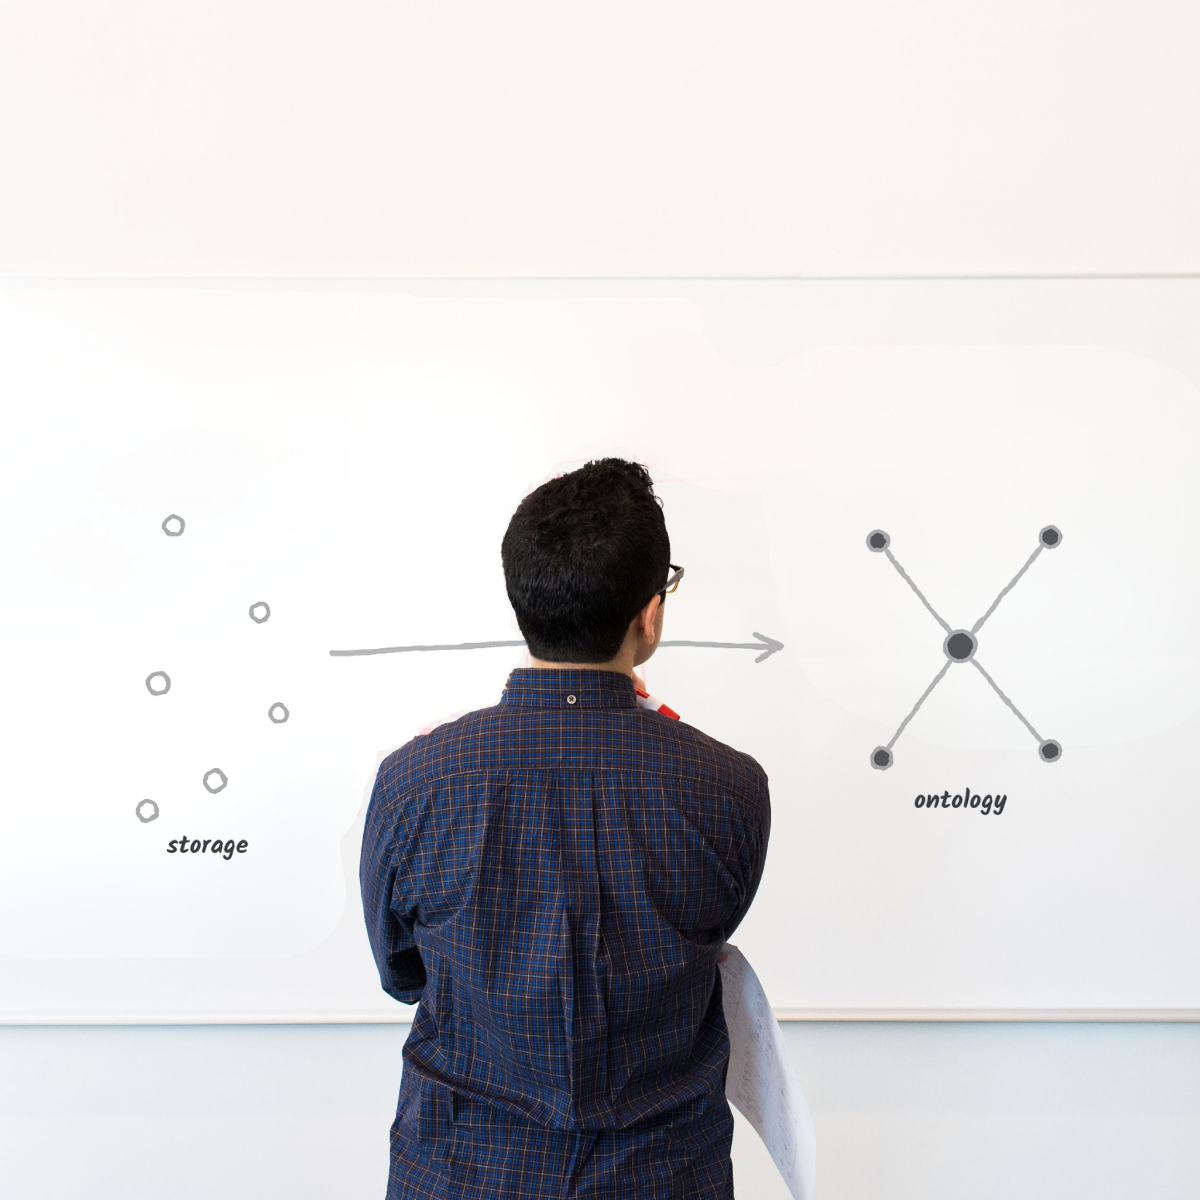
Storing information is only the beginning
Organisations have invested in databases, data warehouses and data lakes to manage their information. These platforms provide essential foundations for storing, accessing and processing data.
Bringing information together, however, does not automatically explain how it fits together.
A shared repository might contain both the supplier’s delay notice and the customer’s contract. It may not tell you that the delayed component is needed for the product covered by that contract. That connection might depend on information held elsewhere.
People and applications still need to establish what is relevant, what it means and how it relates to the question being asked. They also need to know whether it is current and supported by evidence.
For the person assessing the delay, a list of files is a starting point. The useful outcome is a view of the commitments that may be affected, with enough supporting information to decide what to do next.
Why documents are harder to work with
Traditional applications benefit from clearly defined data models. A customer relationship management system, for example, has known concepts such as customers, accounts and contacts. Fields and relationships are designed around the processes the application supports.
That structure makes a question such as “Which orders did this customer place last month?” relatively straightforward to query.
Documents and conversations carry information differently. A single email might mention a supplier, a component, a revised delivery date and a customer concern. Some relationships are stated directly. Others depend on context from earlier messages or other systems.
Representing that information in a structured form is possible, including in relational databases. The difficult work is deciding what to extract, interpreting it correctly and keeping it up to date.
Trying to model every detail in every document can become a substantial maintenance task as formats, terminology and business needs change. A practical starting point is to identify the questions worth answering and the information needed to answer them.
Finding relevant content and connecting the evidence
Many AI assistants use retrieval-augmented generation, usually shortened to RAG. The system retrieves relevant information and provides it to a model as context for answering a question.
This can work well when the answer is contained in a few passages. Asking for the delivery terms in a particular contract is one example.
Our supplier-delay question requires a broader set of connections:
Supplier → component → product → customer order → delivery commitment
Each connection may come from a different source. A passage about a customer order might be essential to the answer even though it never mentions the supplier.
Retrieval needs a way to identify that connection and bring the supporting information together. Graph-based approaches can help by making relationships available to the retrieval process. For example, AWS’s open-source GraphRAG Toolkit combines semantic search with graph traversal to retrieve information that is directly or indirectly connected to a question, including relevant information spread across different sources.
Whether this improves the result depends on the question and the quality of the underlying information. It is something to test against actual business questions.
Shared meaning makes the connections useful
Connecting information also requires agreement about what the information means.
Does “customer” refer to a parent company, a legal entity or an individual account? Is a “delivery commitment” a contractual obligation, an internal target or a date proposed in an email?
Those distinctions matter when assessing the impact of a delay. Treating every mentioned date as an agreed commitment could produce a misleading answer.
Time and source context matter too. A later agreement may change an earlier date. Two documents may conflict. A connection may be explicitly recorded, derived through a defined rule or suggested by a model. These distinctions should remain visible.
An answer people can act on should show which commitments may be affected, the sources supporting that assessment and any gaps that still need review. A link to a document helps, but the cited passage must actually support the claim.
Where ontologies, knowledge graphs and GraphRAG fit
Three concepts are useful here, each serving a different purpose.
An ontology defines the concepts and relationships in a domain, and can include rules about how they relate. It gives systems a shared basis for interpreting terms such as supplier, product and commitment. For example, it might define that a supplier provides components, components are used in products, and customer orders contain products. Formal ontology languages can also support consistency checking and logical inference.
A knowledge graph stores actual entities and their relationships as data. In our example, it could store that Supplier ABC provides Component X123, that Component X123 is used in Product P456, and that Product P456 is included in Customer Order 789. Links to source records and documents can provide evidence for those connections.
GraphRAG combines semantic retrieval with graph-based relationships to find information spread across different sources. In our example, retrieval might identify the supplier delay notice, while graph relationships connect that supplier to affected components, products and customer orders. The system can then retrieve supporting content from those connected sources, such as email threads, contract terms and project updates. It could also surface previous delay communications to understand how similar situations were handled and how customers responded.
Together, these approaches can support shared meaning, connected information and useful retrieval. They can sit alongside existing databases, warehouses and document stores.
The appropriate combination depends on the problem. A focused search application may need little additional modelling. Questions involving many dependencies or inconsistent business definitions may justify more structure.
Start with the business question
The right starting point is the decision an organisation needs to make. What question is difficult to answer today? Where is the supporting information? What would make the answer useful enough to act on?
For the supplier-delay example, success could mean identifying affected commitments faster, reducing missed dependencies and making the supporting evidence easier to review.
The challenge is not simply storing more information. It is making the right information, relationships and evidence available when a decision needs to be made.
In follow-up posts, we will explore how GraphRAG works in practice, look at customer examples and examine where ontologies can add value.
Article written by Vikram Niranjan, supported by Thanga Sivanu.
Talk to Us
We would love the opportunity to connect and understand more about the problems you are trying to solve.
Abhinav Sharma
Partner
Get in touch to coordinate a meeting with one of our technical experts.
Australia: +61 7 3132 3002.